emailmanager.ailive
Answers customer support mail
Drafting, classification, escalation rules
The schedule below is the one that actually runs, times taken from the config. They research, write, grade their own output and file it. Nothing goes out until I say so — that part is still me, and it is the part I am least willing to automate.
Scheduled, not measured. This board reads the timetable, not last night’s logs. When a run fails you read about it in What broke, not here.
Fourteen runs across eighty-five minutes. One dot per run; where two share a minute, they run side by side. The marker appears only while the night is actually under way.
Rereads my own doctrine files and flags the rules that stopped matching reality
Argues with last week’s plan and says where it is now wrong
Takes the opposite side of whatever I decided, on purpose
Checks the whole machine for silent failures — the watchdogs that died quietly
Pulls traffic and search data into the ledger
Researches, writes and files a full article draft
Works the press cycle: who to pitch, what changed, what is stale
Reads the feeds and writes the briefing I read at breakfast
Drafts the LinkedIn post
Drafts the Reddit answer and checks it against the sub rules
Drafts the X post
Grades last night’s output and says what was weak
One idea, argued through, filed as a card
Sorts the inbox and drafts replies for me to approve
By morning there are drafts, a briefing and a grade on last night’s work. I read, cut, and press the one button they are not allowed to press.
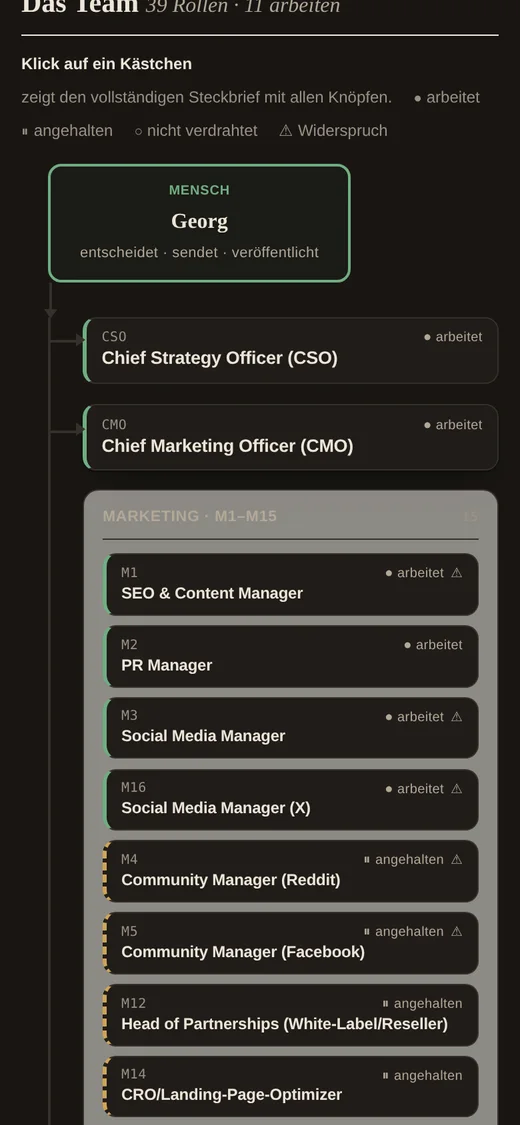
Five are products, five are the machinery that keeps them fed, and one is a gym log with no automation in it at all. All of it runs on hardware I own, and every claim on this site can be traced to a log on it. The pictures are taken by a script, on a phone-sized screen, and retaken whenever something changes.
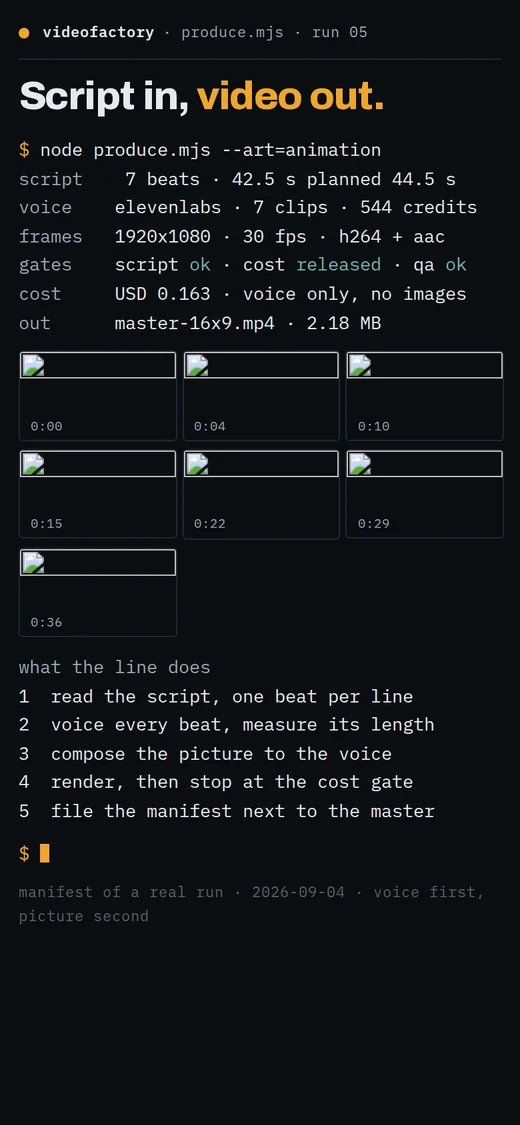
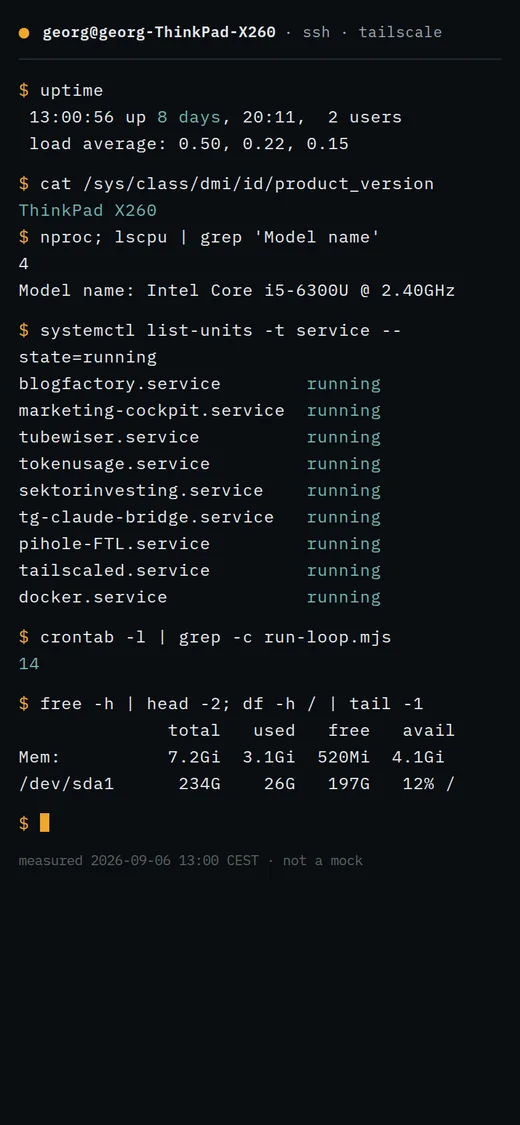
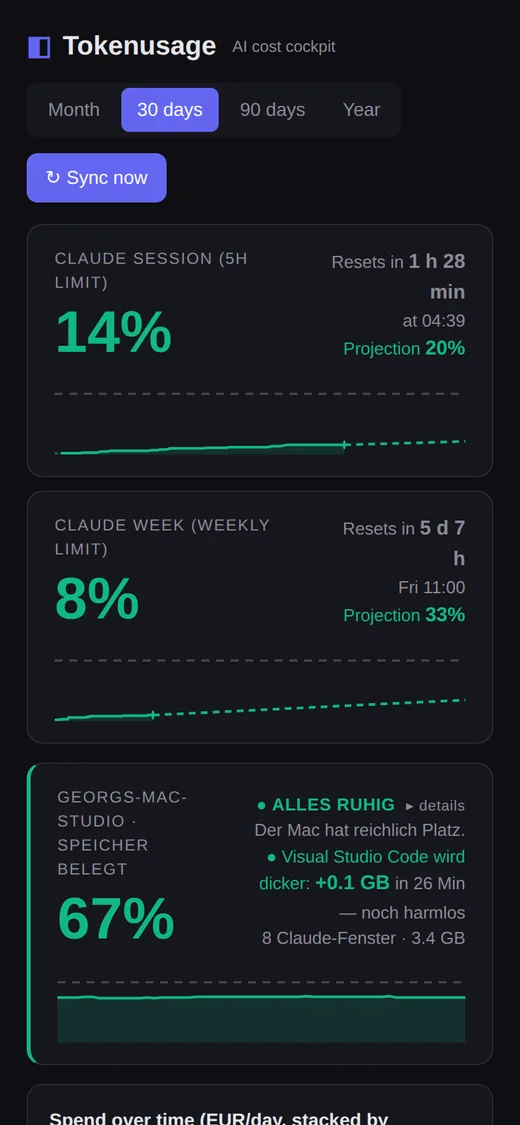
Four strands. Failures get the same room as the wins, because they are the part nobody else writes down.
Reconnecting X fixed its 280-character limit and silently gave the channel a new id. My config kept pointing at the old one.
My code said a post could be 25000 characters. The service in between accepted 280, and it had said so in a rejection nobody read.
I sorted the heap of 121 open proposals my agents had made. 21 became work, 100 were rejected, and each rejection got a written reason.
I switched a card’s project 20 times. Every switch was saved, and the history showed each one as an empty note. The bug sat where the…
A limit I wrote to keep one failure cheap stopped every card for 142 minutes, while three indicators stayed green.
I tested a cron schedule by calling the script the cron calls. It ran for real. What 14 crontab lines taught me about dry runs.
A deadline set to 48 hours ran for 72, because the job that enforced it only looked once a night.
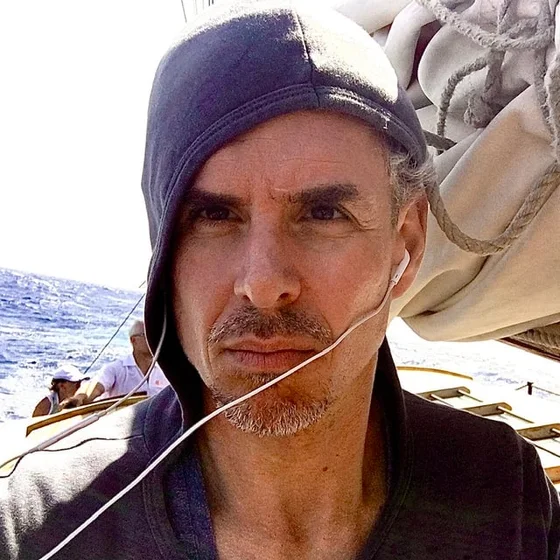
I am Georg Singer. Physics degree, doctorate in computer science. Everything on this site I built myself, in my own time, on hardware I own.
Why this exists at all: I wanted to find out how far it actually goes — whether running my own products can be handed to software almost end to end, from the research and the writing to the bill at the end of the month. The only honest way to test that was on my own things rather than on somebody else’s company, so I am my own experiment. What I am really collecting is the list of what does not work, because that is the half nobody publishes.
Everything here is first-hand. If a number appears, it came out of a log on my machine, and if I could not measure something I write that instead of estimating it. That is the whole editorial policy.
The same three steps on every system above. Not a method I recommend — the order I actually work in, written down because most of what breaks happens between the steps rather than inside them.
Before anything gets built I follow the process as it really happens and write down what it costs me today. Every one of my expensive mistakes started with skipping this and estimating instead.
Only the one or two steps that pay for themselves first. On hardware I own, with logs that prove the run happened rather than a dashboard that says it did.
Automation rots. Every month the watchdogs get tested, the rules get re-measured against what is true now, and the costs get read out loud. Most of What broke is this step failing.