At half past midnight a small program wakes up on a ten-year-old ThinkPad under my desk, decides whether one of my agents should work tonight, and in most cases decides that it should not. I used to think the interesting part of an automation was the part that does the work. It is not. The interesting part is the fourteen places where the work is refused.
I counted them this morning, in the file that starts every run. Fourteen separate points where a run stops before a single token has been paid for. Then, and only then, does anything expensive happen.
That last number is my favourite thing in the log. One millisecond. A run started, was told it was not wanted, wrote down why, and stopped. It cost nothing, and it left a record that it had considered the question.
The board
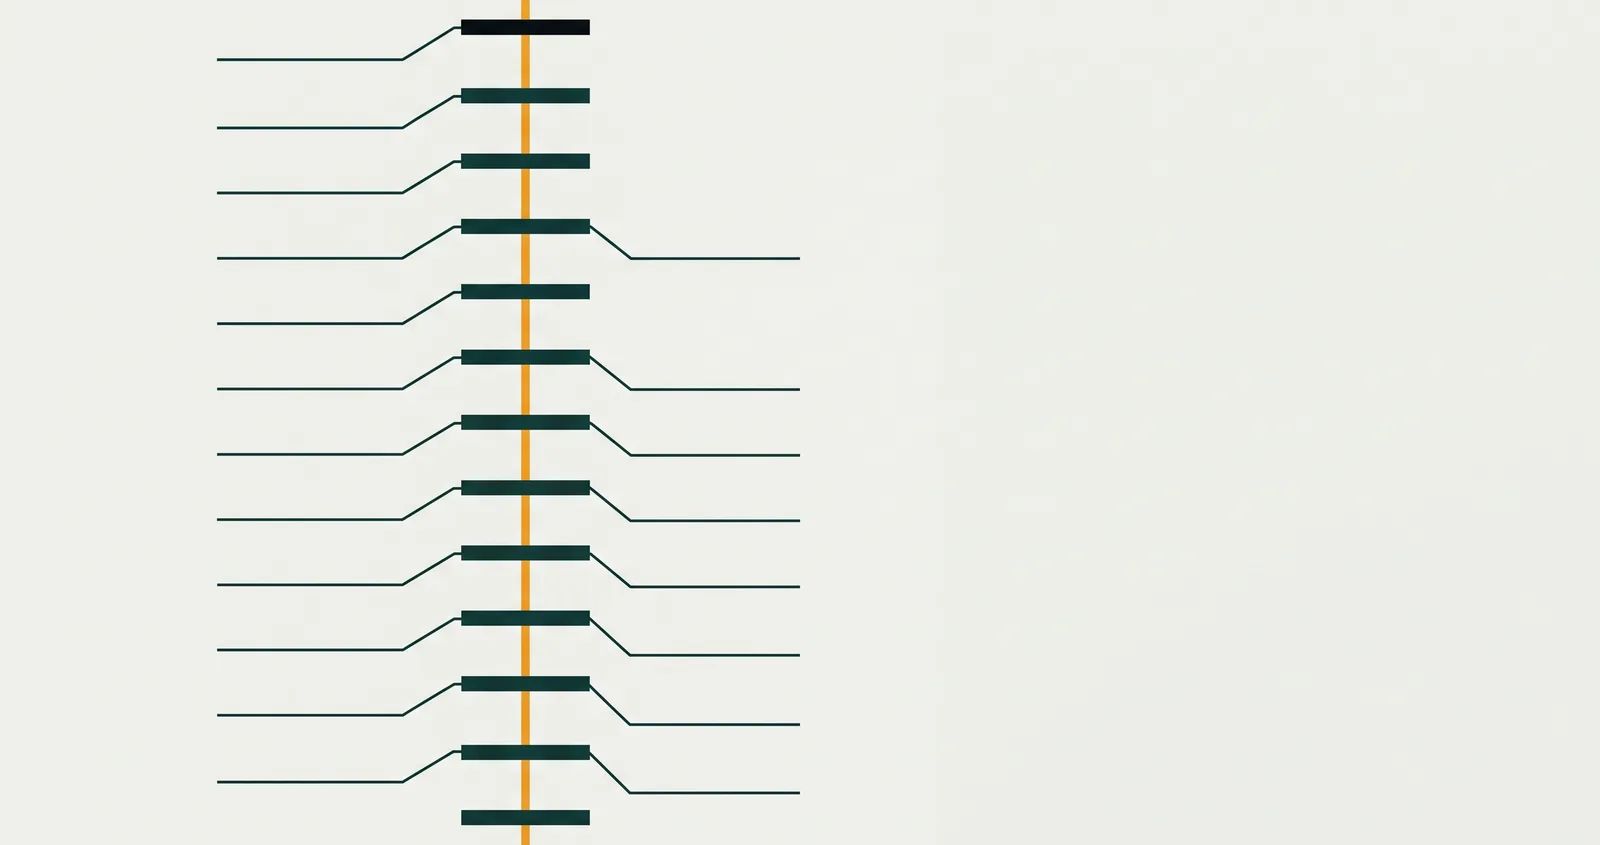
Here is the whole ladder, in the order a run meets it. Read it top to bottom the way the machine does. The right-hand column is the exit code, and it is the only part of this that matters at seven in the morning.
Loud and quiet is the only distinction that matters
When I open the board at seven, I do not want to know how many runs did nothing. Most of them did nothing. I want to know whether any of the nothings needs me.
So the fourteen split in two. Eight of them end with exit code 0, which means: this is a normal night, there was nothing to do, go back to sleep. Six end with exit code 1, which means: I could not even get to the question. Those two things look identical in a list of skipped runs, and they are completely different problems.
Number 9 is there because it once was not. Until the middle of August, a gate whose name the runner did not recognise simply passed. The brake was present in the configuration, absent in reality, and the run started unbraked. A misspelling would have been enough, and nobody would have learned about it. It is now the loudest failure in the list, and it is the only place in this file where a spelling mistake stops a machine.
Number 12 looks like paperwork and is not. The role contract is where the human approval gate lives. If that file will not load, the run could still write a draft, and the draft would have nothing standing between it and the outside world. So the correct behaviour when the rulebook is unreadable is to refuse to work, not to work carefully.
The two you cannot argue with
Eleven of the fourteen can be overridden with a flag when I want to test something by hand. Two cannot, and the reasoning behind that took me a while to accept.
The emergency stop is one. Creating a single file called DISABLED stops every loop, and the override flag does not help. That is the point of an emergency stop. If it can be argued with, it is a suggestion.
The other one is stranger and I think it is the better idea. Some loops are marked as production only. If you start one on the wrong machine, it stops, and the override flag does not help there either. The distinction the code makes is between a question of intent and a question of fact. Whether a loop should run tonight is intent, and I am allowed to overrule it. Whether this machine can run it at all is a fact, and a barrier that gives way to a switch in the face of a fact has stopped being a barrier.
The same file also says why an unrecognised value blocks instead of passing. Write the machine name slightly wrong and it would otherwise quietly become “runs anywhere”. Unknown is not the same as allowed.
Every exit puts the work back
There is a line at every one of the fourteen exits that I got wrong at first and that is the least glamorous thing in this article.
A run usually starts because a work ticket was assigned to it. The ticket is marked as being worked on. If the run then drops out at check number 6, and nobody unmarks the ticket, the ticket sits there claiming to be in progress until a cleanup process notices the lease has expired. Meanwhile the board shows a job in progress, and the next run finds the ticket occupied and refuses too.
So all fourteen hand the ticket back on the way out, with the reason attached. It is fourteen nearly identical lines of code and it is the difference between a quiet system and a system that appears to be failing.
The third way a run can end
For a long time a run had two possible endings. It ran, or it failed. Both of those assume that an agent actually worked.
On a morning in August neither was true. The login for the model had expired overnight. Three runs ended after a couple of seconds with a failure code, and the board reported three broken automations. Nothing was broken. The workshop was shut.
Those two in the bottom row are the reason the category exists. A failure and an outage need different responses from me: one is a bug to fix, the other is a login to renew, and until they had different names they produced the same red box.
The detection is deliberately narrow. It reads only the last twelve lines of output, and a pattern has to start the line. The reasoning is nice: a sentence that talks about an error mentions it in the middle. A process that is dying puts it at the front.
What I would check in your setup
If you run anything on a schedule, three questions from this list transfer, and none of them need my code.
First: when your job decides not to work, does it say so anywhere? A scheduled job that exits silently when it has nothing to do is indistinguishable from a scheduled job that is no longer running at all. That was the one-millisecond entry in my log. It cost nothing and it proved the machine was awake.
Second: can you tell a “nothing to do” from a “could not even start”? If both end the same way, you will learn about the second kind late, and probably from a customer.
Third: take one of your safety checks and misspell the thing it is checking for. If the check still passes, it was never a check. That is the entire content of number 9 on my list, and finding it took one deliberate typo.
None of this makes the agents better at their jobs. It makes the mornings honest, which turned out to be the part I could not buy.
All numbers were measured from the repository on 6 September 2026, not estimated. The fourteen exits were counted in the source of the runner by listing every point that writes a ledger entry and then ends the process before the model is called. The loop counts (26 configured, 17 on) and the daily cap of 30 come from the loop configuration file. The run outcomes come from the runs table of the operations database on my workshop machine, which is a small sample: production runs on a separate machine. The one-millisecond run is the shortest duration recorded in the run ledger.