On 2026-09-12 my blog pipeline ran two complete builds on two different models. Both produced a finished post, and neither post shipped. Each had exactly one hard finding, and it was the same finding both times. One check required the terminal quote to be copied word for word from the fact sheet, and the transcripts in the fact sheet are German. Another check required that same field to be English. If the writer quoted the transcript exactly, it failed the second check. If it translated, it failed the first. No post with a terminal block could pass both, however it was written.
The goal was easy to state. The chain writes a post from a fact sheet, a set of gates checks it, and if every gate is green the post goes out by itself after 48 hours unless I veto it. That only works if the gates can all be satisfied at the same time. A gate that nothing can pass is not strict. It is a wall dressed up as a standard.
I believed that two rules that each make sense alone would still make sense together. The language rule was right: this site is read in English, and a German sentence in a paragraph is a defect. The verbatim rule was right too: a transcript I reconstruct claims a machine said something it never said. I had written each rule, tested each one, and watched each one catch real problems. I never asked what happens when both of them look at the same field.
Both checks read the same field and expected opposite things. The verbatim check compared the terminal text against the transcript on the fact sheet, character by character. The language check required every field the writer produced to be English, and it treated that field like any other. Neither check knew about the other. From the outside, an unsatisfiable pair looks exactly like a weak post. The obvious reaction is to rewrite the post, and here no rewrite could ever help.
The exception already existed. Quoted commit subjects are German too, and the language check had let them through for a long time, for the same reason: a quote is evidence, and translated evidence stops being evidence. The renderer marks those quotes as German, and the draft step strips the marked text before it counts German words. Nobody had extended that exception to the terminal field. One field got the reasoning and the field next to it did not.
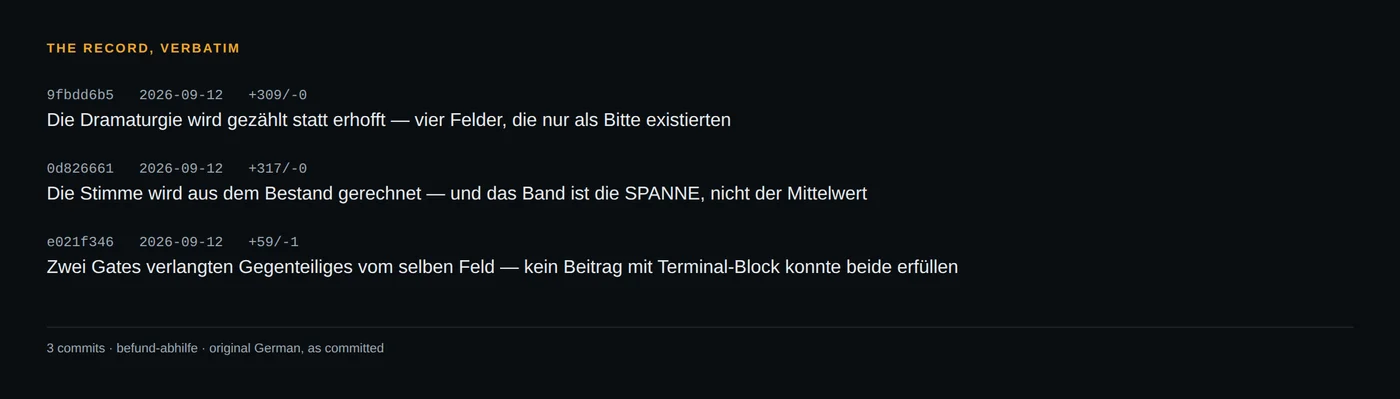
Zwei Gates verlangten Gegenteiliges vom selben Feld — kein Beitrag mit Terminal-Block konnte beide erfüllen
Two gates demanded opposite things from the same field — no post with a terminal block could satisfy both
How I got there
Earlier that morning I had added two other checks to the same chain. They explain why I was reading gate results closely that day, and both of them came from the same distrust of rules that exist only as a request.
Die Dramaturgie wird gezählt statt erhofft — vier Felder, die nur als Bitte existierten
The story structure is counted instead of hoped for — four fields that only existed as a request
Die Stimme wird aus dem Bestand gerechnet — und das Band ist die SPANNE, nicht der Mittelwert
The voice is calculated from the published posts — and the band is the RANGE, not the mean
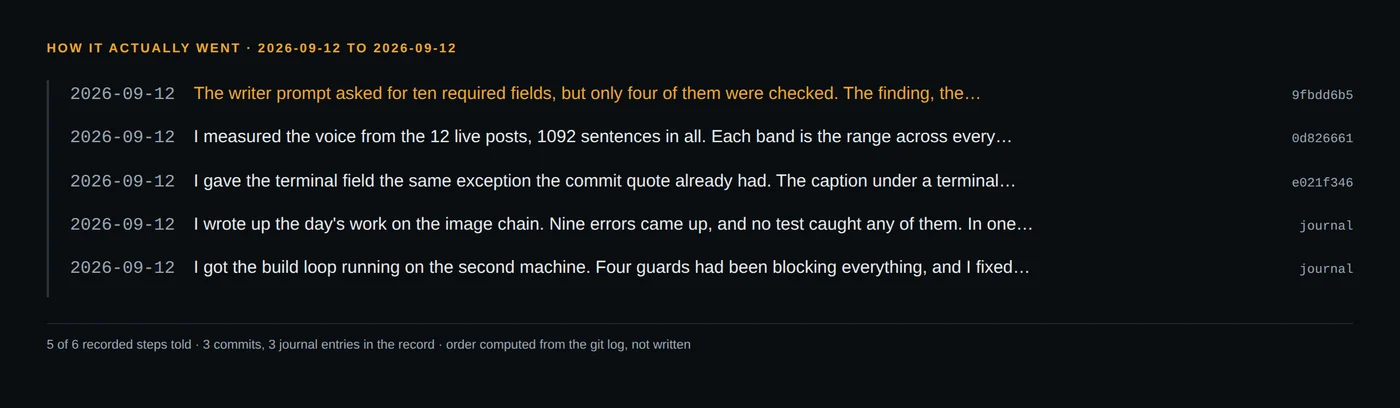
- 2026-09-12The writer prompt asked for ten required fields, but only four of them were checked. The finding, the belief, the mechanism and the outcome lived only as a request in the prompt, and nobody measured them. I didn’t ask a model to judge whether they were present, because the critic I had built that way flipped 5 of 20 cases at its threshold. The writer now emits those fields as named sections, so a missing one shows up as a count of zero. 16 tests.
- 2026-09-12I measured the voice from the 12 live posts, 1092 sentences in all. Each band is the range across every post, not a band around the mean, because a band around the mean would have blocked a post that is already published. Only the title form blocks. On its first real run the check found that a machine-written post had a median of 26 words per sentence, which put it outside all three bands. 10 tests.
- 2026-09-12I gave the terminal field the same exception the commit quote already had. The caption under a terminal block is still my prose and is still checked for language, and a test holds that line. After the fix, the same build passed every gate on the first try and became post #515.
- 2026-09-12I wrote up the day’s work on the image chain. Nine errors came up, and no test caught any of them. In one of them, the commit hash printed next to each sentence was matched by list position instead of by reference. It came out right only because the first steps happened to be in the same order as the commits.
- 2026-09-12I got the build loop running on the second machine. Four guards had been blocking everything, and I fixed each one at its cause. One post was built and scheduled to go live.
The structure check taught me something about precision. The finding has to carry a figure from the fact sheet, and the match runs on the digit sequence, not on equality. If the sheet says 71, the post may write 71 of 71. And 7 must not be found inside 71. A substring comparison would have been a gate that measures the wrong thing, and it would have looked fine in every test that only checked the happy path.
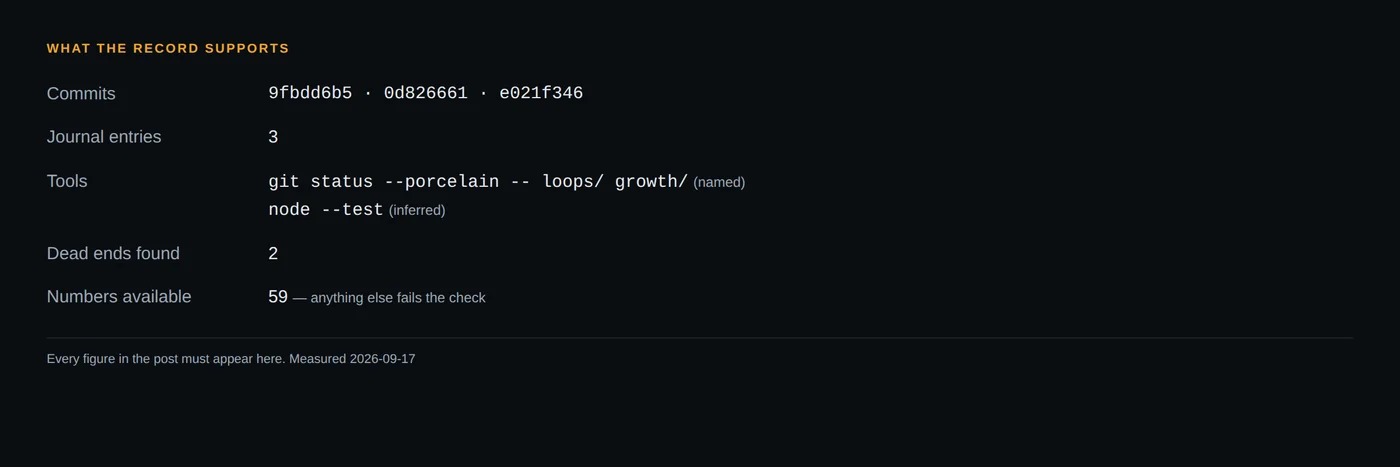
The record names one command I said I used: `git status –porcelain — loops/ growth/`. It came from a neighbouring deploy, where I had to wait until another session’s uncommitted modules were gone before I could ship. All three commits also changed test files, so a test runner was almost certainly involved. That is inferred from the changed files. The record does not say I ran it.
The dead end came first, and it was the old way of handling the story itself. Four of the ten fields existed only as a polite request in the prompt, and nobody measured them, including the one the prompt itself calls the source of the drop. I also decided against the obvious fix of asking a model to judge. A judge whose verdict flips on a quarter of the cases at the line is a dice roll with a rubric.
It ended solved, for this pair. The two expectations are now separate. The terminal quote may be German because it has to match the transcript, and the caption beside it still has to be English. The story structure is counted instead of hoped for. The voice comes from the published posts as a range, not an average. The fix leaves some things uncovered. The hole is smaller than for commit quotes, because the verbatim match blocks anything that is not in the transcript, but the language check no longer looks inside that field. I also found this pair by running real builds, not with a test that puts all the gates against one input. The record does not show such a test.
I had already named one cost in the structure commit, before the conflict came up at all. Post #489 was already announced through card #519 and did not have the four new fields. The new gate would stop it until it was rebuilt. That is fail-closed and correct, but it meant the post would not go out in that form.
Three commits on 2026-09-12, plus the handover notes from the same day. Fact sheet measured on 2026-09-17. The cost record covers every run in the window, not just this topic, so treat it as an upper bound.
9fbdd6b5 · 0d826661 · e021f346